We have two new publications out!
- Disconnect between the public face and the voting behavior of political representatives by Christian Ivert Andersen and Michele Coscia, published in the journal Applied Network Science.
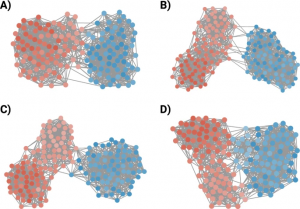
One of representative democracy’s tenets is that a political candidate runs on a specific platform, which is information the electorate uses to determine whether to vote for them or not. If this promise is to be maintained, it is fundamental that the public face candidates present corresponds to their actions in parliament once elected. Such a promise has been put in question both by scholars, but also by the electorate. In different countries at different times, the people have expressed various degrees of dissatisfaction with democracy: often the feeling is that representatives put their own interests—or the interest of a powerful minority—before the ones of their constituencies. In this paper, we propose a network-based quantitative investigation of this disconnect between the public face and the voting behavior of elected representatives. By using data from Denmark, we can place politicians in two different spaces, determined by their electoral campaign promises on the one hand, and on the other hand by the votes they cast in parliament. We find that our technique makes it possible both to find clear, expected, and consistent left-right divides between the political parties; as well as a larger-than-expected disconnect between the public face and the voting behavior. Our preliminary results indicate that the aggregate voting behavior in parliament of politicians does not match with how they present themselves to the public on the salient issues discussed during the election campaign. - Evaluating fraud detection algorithms in a decentralized scenario by Ada M Gige, Lasse Buschmann Alsbirk, Michele Coscia, published in the journal Royal Society Open Science.
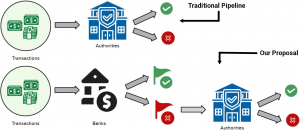
Financial fraud is an umbrella term including a vast number of illegal activities. These activities involve a significant fraction of the global economy. Traditional investigation techniques are labour-intensive and cannot scale to match the size of the issue. Machine learning has provided effective tools which deliver high accuracy in identifying transactions that could be involved in fraudulent activities. In this paper, we point out that the state-of-the-art in financial fraud detection has been applied to the unrealistic scenario of an omniscient centralized global authority which has access to all bank transactions globally. We propose a more realistic evaluation scenario, one made of two steps: first, the bank flags its own transactions using exclusively information it possesses; then only flagged transactions from all banks are analysed by the governmental authority for potential prosecution. We find that, in such a realistic scenario, the effectiveness of the state-of-the-art method for financial fraud detection decreases. Moreover, we show that in this decentralized scenario, it pays off to use simpler methods than the state-of-the-art, depending on the specific objective function the system wants to ensure.
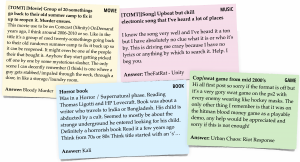 Users often turn to online forums when searching for known books, movies, or games that they cannot identify through conventional search engines. These “tip-of-the tongue” requests present a unique challenge, appearing highly variable in formulation, context, and specificity. So far, these could mostly only be solved by other humans answering in forums. Generative AI is believed to help solve these specific questions. In this work, we manually annotated 150 requests each for books, games, and movies in the casual leisure domain to study the differences between solved and unsolved requests and identify factors that influence their difficulty. We compare human responses in forum threads with the performance of a Large Language Model (LLM) under similar conditions. Specifically, we investigate how the formulation of requests affects human and LLM success; how item properties impact LLM retrieval; how interaction and feedback within a thread shape human and LLM performance; and whether increasing the information provided to an LLM improves its chances of solving the request. Our findings offer new insights into what makes these known-item search problems easier or harder to solve. This study contributes to a better understanding of complex search behavior and the role of LLMs in helping with difficult casual-leisure information needs.
 Jacob joins us as a new postdoc, bringing degrees in mathematics and extensive experience with data‑driven modeling of epidemics.