New NERDS paper on investigating the robustness of a Danish voting advice algorithm

Last month Giovanni Astante (who worked on the topic during his research stay at NERDS) presented our work (w. Roberta Sinatra) on “Investigating the Robustness of a Danish Voting Advice Algorithm” (VAA) at the European Conference on Algorithmic Fairness.

Now the paper is finally out in the Proceedings of Machine Learning Research!
You can find a copy here –> https://proceedings.mlr.press/v350/astante26a.html

We look at a popular VAA (called ‘Kandidattesten’), developed by the large media house Politiken, and investigated the robustness of its matching algorithm.

In past Danish elections 62% of eligible voters used some form of voting assistance algorithms (‘Valgtest’ in danish) one month prior to the election and 45% reported they followed the recommendation of a VAA when voting. This means these voting tools can have a large influence on election results.

Through a freedom of information request we got access to the algorithm used to match users and political candidates. The system functions by users filling out a questionnaire which is compared to a database of answers from candidates. Users are then presented candidates with highest agreement.

These systems have been studied in the past (mostly how humans interact with them), but so far nobody has tested their robustness. We study how minor modifications to the algorithm’s weights can change the outcome of which political candidates are recommended. In addition, we study how dropping questions, i.e. calculating match similarity based on fewer questions (than the original 20), affects which candidates are recommended.

Our results demonstrate that even minor tweaks to the algorithm can produce entirely different outcomes, potentially affecting outcomes of political elections. A marginally changed matching algorithm can recommend entirely different political candidates, from different political parties.

Based on our findings we provide recommendations to VAA developers and policy makers, on how to monitor and evaluate the robustness of these systems.
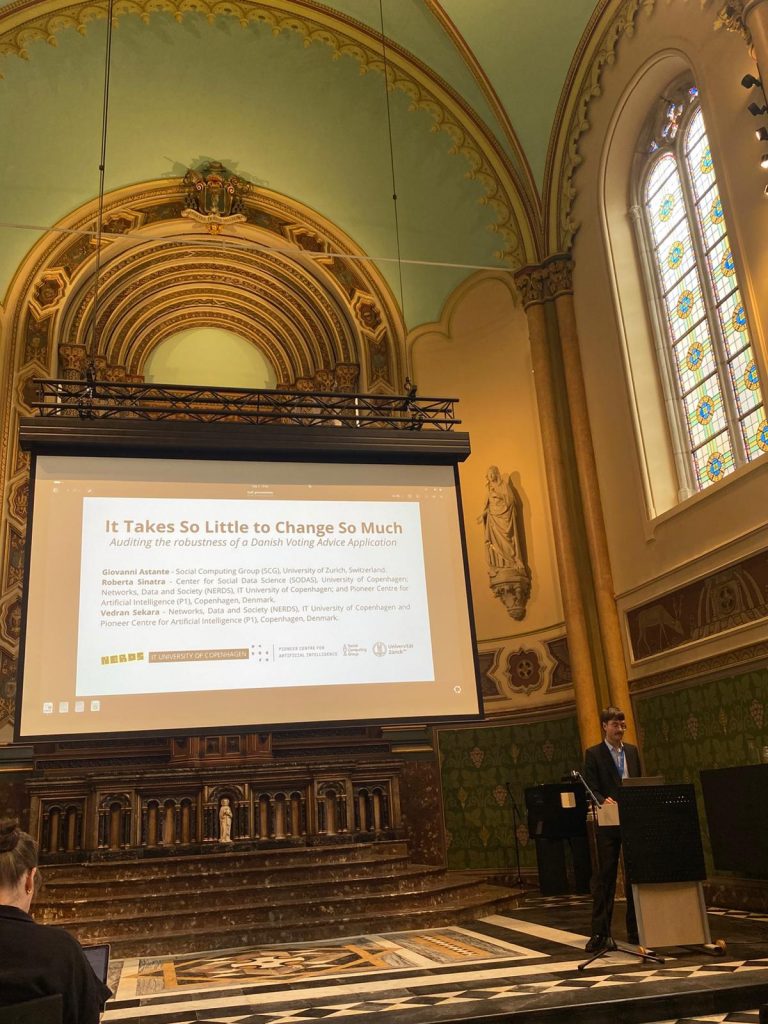
Giovanni Astante presenting our work at ECAF 2026, in a fantastic auditorium

New NERDS paper on the effectiveness of epidemic mitigation strategies

New NERDS paper out! Congratulations to our PhD student Morten Rahbæk Boilesen on publishing his first article!

Are fast test results preferable to high test sensitivity in contact-tracing strategies? This question is addressed by Morten Rahbæk Boilesen, Kaare Græsbøll and Jonas L. Juul in their modelling study of the dynamics of contact tracing, testing and isolation strategies in epidemic outbreaks. Here is a description of their paper:

During disease outbreaks, public health officials might face a decision on whether to use rapid tests that give quick but sometimes inaccurate results, or slower and more precise tests. This choice matters because delays in diagnosis slow down contact tracing, allowing infected and their potential secondary infections to spread illness longer.

Here, we use mathematical modeling to examine the trade-off between test speed and test accuracy. We use the mathematical model to simulate epidemic outbreaks with different levels of contact tracing efficiency, test turnaround time and test sensitivity. In each case, we evaluate whether disease mitigation is best with slow-and-accurate tests or fast-and-inaccurate tests.

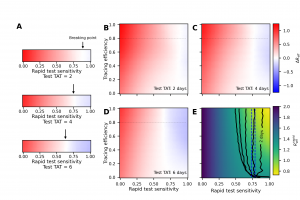
For diseases similar to COVID-19, we find that accurate tests with test turnaround time less than four days generally reduce transmission better than rapid, less reliable tests. However, when contact tracing is highly efficient, faster results become advantageous.We show that if test sensitivity is proportional to the viral loads of the infected, rapid tests become more favourable overall as opposed to modelling the test sensitivity as a constant value independent of the viral loads of the infected.

Finally, our analysis shows that when contact tracing isn’t feasible, neither rapid nor accurate testing outperforms simply having people self-isolate without testing infrastructure.

This work can help guide testing strategy decisions when an epidemic is raging, revealing that prioritizing speed can become a viable strategy to reduce transmission when testing infrastructure is under stress.

A figure showing effective reproduction number under mitigation strategies.

Anthony Zhou has joined NERDS


Anthony Zhou has joined NERDS as a Research Assistant in the FemVision Project. Anthony recently graduated from the Social Data Science Msc Program of Copenhagen University and has a Bachelor in Public Health and Data Science from the University of Washington.  Anthony has experience both with complex data pipelines as well as in studying  Illicit maritime networks.

We’re happy to have you on board, Anthony!

Anders Giovanni Møller defends his PhD: “AI in Modern Society: From computational methods to societal consequences”

Big congratulations to Anders for successfully defending his PhD thesis on how AI is changing Computational Social Science and the Web. The Committee was composed by Elisa Mekler, Robert West, and Johannes Bjerva. His very proud supervisor is Luca Aiello.

During his three years with NERDS, Anders has published 6 papers in the areas NLP and CSS, pioneering topics such as synthetic data generation with LLMs and AI persuasion. His graduation officially concludes the COCOONS project.

Anders has now started a job in the industry as AI Lead of Polaris, in Copenhagen.

In bocca al lupo, Anders!

CS2Nordics was a blast!

The first edition of CS2Nordics has been a smashing success, with 130+ participants and a strong presence of 26 members of NERDS presenting talks and posters. The conference was organized by Luca Aiello at NERDS in collaboration with Laura Alessandretti (DTU) and Florian Meier (AAU). Once again, we give huge thanks to the sponsors: IT University of Copenhagen (especially the Data Science Section), DDSA, Pioneer Centre for AI, and Aalborg University of Copenhagen. Stay tuned for the next chapter!

New NERDS paper on Narrative Polarization

Measuring narrative polarization in online discourse by Jan Elfes, Marco Bastos, and Luca Maria Aiello, published in PNAS Nexus.

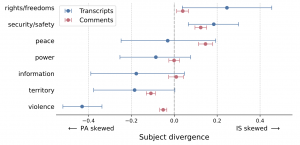
Subject divergence in comments and transcripts. Subject divergence refers to differences in how partisan information environments attribute the Subject role to different conflict actors. Shown are the attribution patterns for various Objects. Values near zero indicate low divergence, reflecting similar attribution patterns across environments. Negative values reflect greater attribution by the Israeli-leaning environment (relative to the Palestinian-leaning environment) to Palestinian actors, whereas positive values reflect greater attribution to Israeli actors. Error bars represent 95% bootstrap CI (n= 3,000).

We introduce narrative polarization as diverging representations of key actors through their positioning in popular narratives. For example, a representation of Palestinians as a people striving for rights and of Israel as a violent actor favors interpretations of violent actions by Palestinians as resistance. In contrast, a focus on the struggle of Jews to escape historical persecution and of Palestinian groups as a constant violent threat might render the same actions as terrorism. Such structural differences in how actors are positioned shape the information landscapes that audiences navigate and affect their opinions. We showcase this by measuring narrative polarization around the Israeli-Palestinian conflict on YouTube. We find that, while videos produce highly polarized narratives, comments converge on a shared narrative distribution, offering less polarized narrative representations.

Marcus Friis has joined NERDS

Marcus joins us as a new PhD Student. With a background in Data Science, and experience from the danish news media Politiken, he is a perfect fit! Marcus also plays the trumpet in his free time. He will work with Vedran Sekara on uncovering how climate change impacts human behaviors.

Marcus will work on the Climate Adapt project funded by Independent Research Fund Denmark (DFF) and we hope insights from the project will ultimately provide data-driven recommendations to policy makers on how to design effective responses to climate change.

We are thrilled to have you on board, Marcus!

New NERDS paper in PNAS! More is different in AI multiagent systems

Group size effects and collective misalignment in LLM multi-agent systems by Ariel Flint, Luca Maria Aiello, Romualdo Pastor-Satorras, and Andrea Baronchelli, published in PNAS.

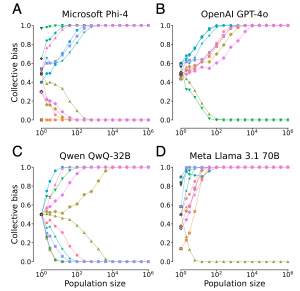
As AI agents begin to operate in populations rather than one at a time, our new research suggests that the number of them changes what they collectively decide — amplifying a bias, inventing one from nothing, or flipping a group into the opposite of what each agent would choose alone. When artificial intelligence (AI) agents interact in groups, their number is not merely a technical detail. It is a decisive factor in what the group settles on: populations built from the same AI model, doing the same task, can reach opposite outcomes for no other reason than that one group is bigger.

In this work, we experimented with populations of LLM agents playing the “naming game”, a classic framework for studying how conventions emerge, in which randomly paired agents each pick a word from a shared pool and are rewarded when they happen to pick the same one. Agents see only their own recent interactions, never the wider population, and are never told they are in a group. Over many pairings, a population can converge spontaneously on a shared convention.

We found that interactions can pull a group away from what its members individually want in three ways. It can amplify an existing leaning until the group converges on it almost every time. It can induce a preference out of nothing, with populations of individually neutral agents reliably favouring one word over an equally viable alternative. And it can reverse a preference outright, so that a population settles on the word its own members disfavoured. Group size then determines how strongly these preferences bite, in ways that cannot be extrapolated. Larger populations became more predictable across every model and word pair tested, converging on one word until the outcome was effectively certain. But the size at which that tipping point arrived varied enormously: for some combinations as few as two agents, for others around ten thousand.

Overall, our results demonstrate that more is different for LLM populations: The number of interacting agents is a key driver of the dynamics, with implications for the design and governance of multi-agent AI systems.